Generating anime art with Waifu Diffusion
Four prompts, four outputs, and how hard it was to tell them apart from a person's work.
Generating images with AI had just got everyone's attention, so I spent a weekend pointing it at something and seeing what came back.
Getting it running was the easy part. There is a web interface fork of Stable Diffusion on GitHub — AUTOMATIC1111/stable-diffusion-webui — which works out of the box with almost no configuration. Rather than the model it suggests, I pointed it at Waifu Diffusion, which describes itself as "a latent text-to-image diffusion model that has been conditioned on high-quality anime images through fine-tuning". Read that as: take a diffusion model, point it at a lot of good anime art, and it gets better at anime art.
Here are four of the results, with the prompt that produced each. Most of the prompts started as a search result and were edited from there. Every image is the model's first pass, at 512×512, with nothing cleaned up afterwards.
1girl, brown eyes, beanie cap, black hair, closed mouth, earrings, hat, hoop earrings, jewelry, looking at viewer, shirt, short hair, simple background, solo, upper body, blue shirt
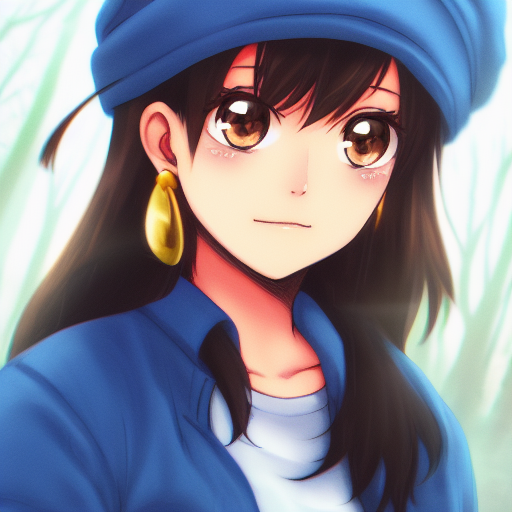
1girl, brown eyes, beanie cap, black hair, closed mouth, earrings, hat, hoop earrings, jewelry, looking at viewer, shirt, short hair, simple background, solo, upper body, yellow shirt
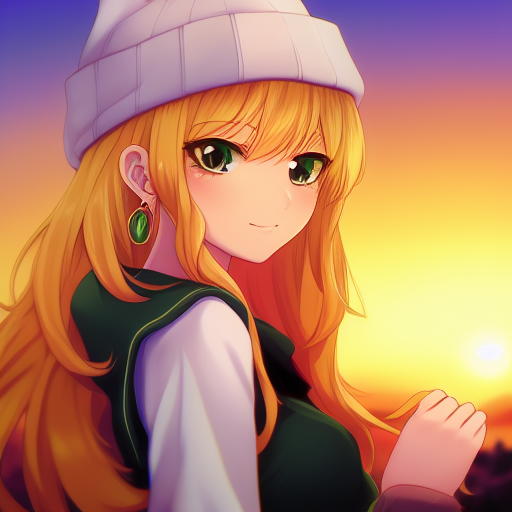
1 girl, sitting on a chair, wearing school uniform, beanie cap, blue jacket in a classroom wearing glasses, black hair, brown eyes, head shot, high resolution, hyper detailed, portrait, soft lips
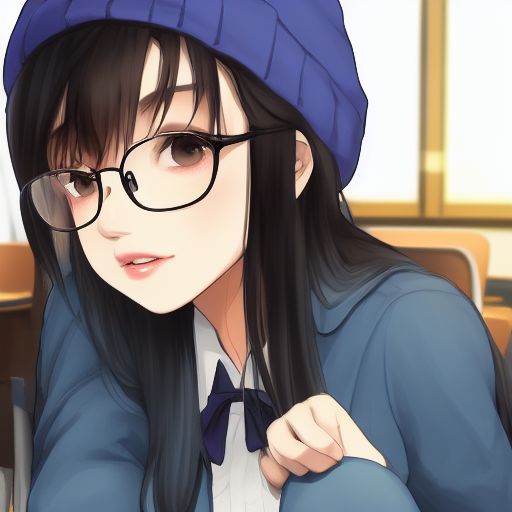
gorgeous young Japanese girl sitting by window with headphones on, wearing blue jacket, soft lips, beach blonde hair, octane render, unreal engine, photograph, realistic skin texture, photorealistic, hyper realism, highly detailed, 85mm portrait photography, award winning, hard rim lighting photography
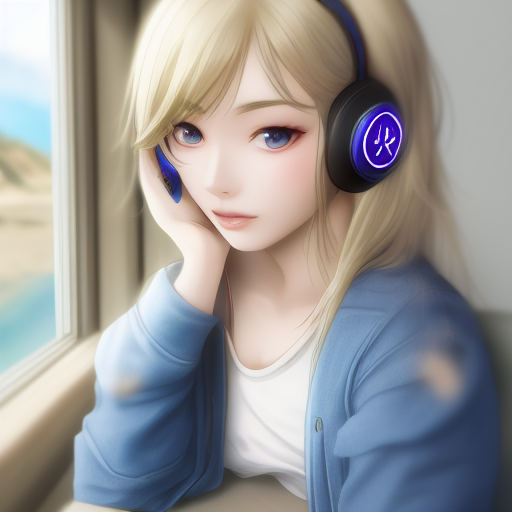
The last two prompts are where it gets interesting. Asking for a "photograph" instead of an illustration changes not just the style but the whole register of the image — the fourth is the same model, and nothing like the first three.
What surprised me is how hard it is to tell these apart from work a person made. All four took seconds.
References
- AUTOMATIC1111/stable-diffusion-webui — the web interface used here.
- Waifu Diffusion — the fine-tuned model.
- Best 100 Stable Diffusion prompts — where several of the prompts above started.
Bye.
Written in 2022, ported from the old Hugo site and lightly edited. The four images are the originals, at the 512×512 these models produced then.
Comments
Discussion lives on GitHub — you'll need a GitHub account to post.